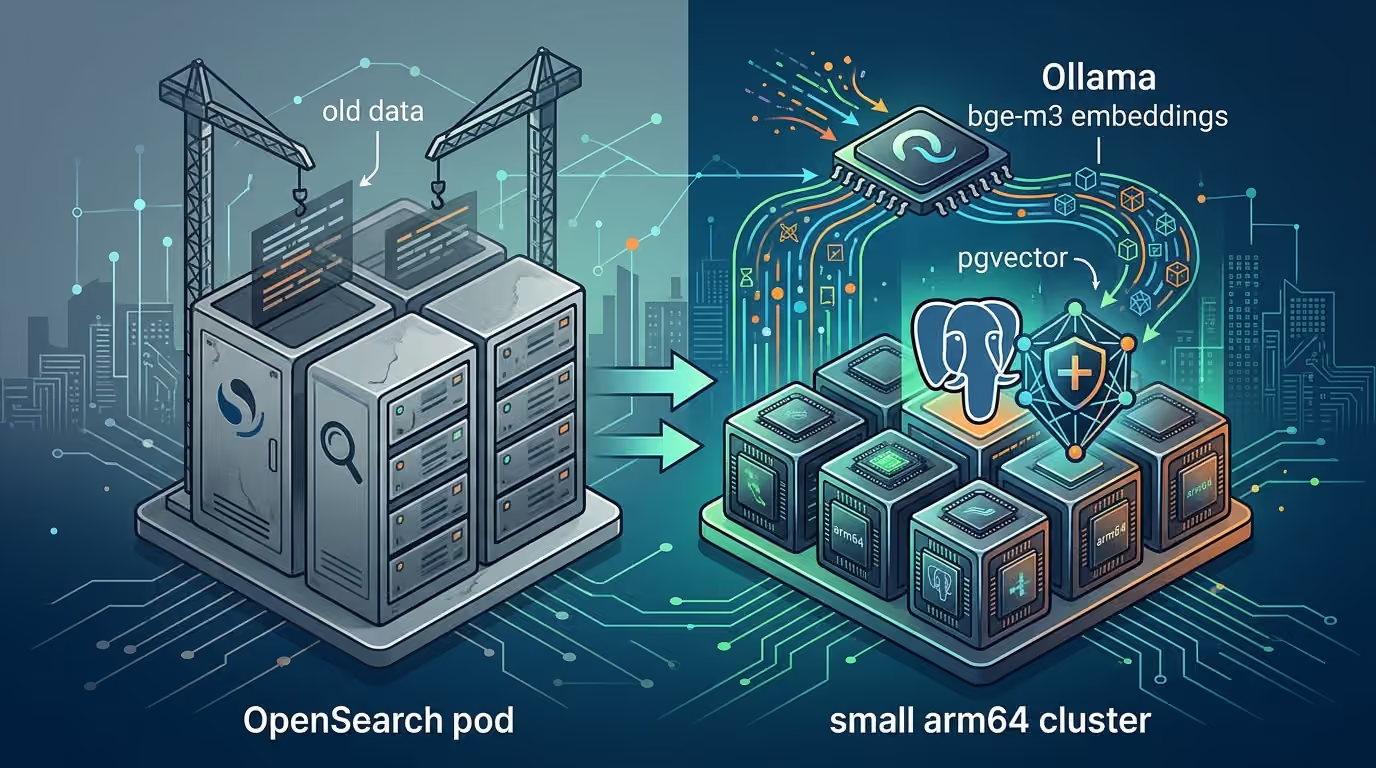
Every embedding-based feature on this site comes from one service, seo-agent: the Python service next to the moks-cms web app that runs Ask the Blog, the CrewAI flows and the news desk. Until now it has embedded everything with bge-small-en-v1.5, an ONNX model of 384 dimensions bundled in its image. The cluster now runs bge-m3 (1024 dimensions) as a shared service, and moving seo-agent onto it looks like a one-line change:
EMBEDDINGS_PROVIDER: onnx # → ollamaIt isn't. The model's vectors end up in a pgvector column whose type depends on the model. Five similarity cutoffs were tuned on bge-small's cosines. And the news desk stores vectors and trains a classifier on them. Changing the model is a data migration, and this post is about treating it as one.
The model service itself (Ollama on arm64, pinned weights, who may call it) is covered in the MOKS article (opens in a new tab). This one starts at the moment seo-agent sends its first request.
Where embeddings live on this site

Two parts of seo-agent embed text, and they store vectors differently.
Ask the Blog answers questions from my articles. Its index is seo_article_chunks, a pgvector table: 2,117 chunks from 45 articles at the last evaluation run. Questions are embedded with the same model and compared by cosine, and a floor (ask_min_score) drops weak matches before a paid model sees them. How that floor is measured is the subject of the RAG evaluation article (opens in a new tab).
The news desk reads technology feeds, drops duplicates, groups items about the same story into clusters, checks drafts for paraphrasing, and tags clusters with topics. It stores a vector on every item and a centroid on every cluster, and four cutoffs decide what counts as "the same".
Why moks-cms needed no migration
moks-cms, the web app, owns the database schema: every table comes from its migrations. A model change could have meant a migration there too, but two earlier decisions avoided it:
-- moks-cms src/db/migrations/0017_news_desk.sql (excerpt)
-- Embeddings are real[] (not pgvector): the extension is optional in this cluster ...
"embedding" real[],# moks-seo-agent app/index.py (docstring, excerpt)
# `seo_article_chunks` is owned by this service rather than by the web app's migrations because its column type
# depends on the embeddings model (vector(384) for bge-small, 768 for nomic-embed-text, …)The news vectors are plain arrays of any length, and the one table with a model-shaped column belongs to the service that knows the model. So all the work was in seo-agent.
Step 1: make the Ollama provider fit bge-m3
seo-agent already had an Ollama provider. It had been written for nomic-embed-text: it added nomic's search_query: and search_document: prefixes, assumed 768 dimensions, and sent a whole article in one request. On mk4's CPU, bge-m3 embeds about 0.7 chunks a second, so one article's 40 chunks in one request would take about a minute.
The new provider knows each model's prefixes and size, sends batches, and checks every answer:
# app/embeddings.py (excerpt)
OLLAMA_MODELS: dict[str, tuple[str, str, int]] = {
    "nomic-embed-text": ("search_query: ", "search_document: ", 768),
    "bge-m3": ("", "", 1024),  # no instruction: the model card embeds queries and passages alike
}

class OllamaEmbeddings:
    BATCH = 8
    RETRIES = 2

    async def embed(self, texts: list[str], *, query: bool = False) -> list[list[float]]:
        prefix = self.query_prefix if query else self.passage_prefix
        out: list[list[float]] = []
        async with httpx.AsyncClient(timeout=self.timeout_s, transport=self.transport) as c:
            for b in range(0, len(texts), self.BATCH):
                batch = [prefix + t for t in texts[b : b + self.BATCH]]
                vecs = await self._post(c, batch)
                if len(vecs) != len(batch) or any(len(v) != self.dim for v in vecs):
                    raise ValueError(f"{self.name} returned {[len(v) for v in vecs]} for {len(batch)} inputs; expected {self.dim} dimensions each")
                out.extend(_normalize(np.array(vecs, dtype=np.float32)).tolist())
        return out
A few details matter more than they look:
- Unknown models fail at start-up. Any model not in the table needs
OLLAMA_EMBED_DIM. A guessed dimension would create a table of the wrong type. - The size check is strict, because the pgvector column and the news desk's stored vectors both depend on it. A wrong-sized vector should fail loudly at the provider, not quietly in a cosine.
- Retries are selective. A dropped connection or a 5xx (the pod restarting, the mesh reconnecting) is retried after 2 s and then 8 s. A timeout is not: the batch has already had its 300 seconds, and three of them would hold a reindex for 15 minutes.
Step 2: cutoffs belong to the model
A cosine of 0.80 means something different for every model. bge-small packs related texts into a narrow band near 1, while bge-m3 spreads them out. So every cutoff that compares two vectors is really a property of the model that made them, and the code now says so:
# app/calibration.py (excerpt)
@dataclass(frozen=True)
class Calibration:
    ask_min_score: float
    cluster_join_cosine: float
    cluster_entity_cosine: float
    dedupe_semantic_cosine: float
    paragraph_cosine: float

BGE_SMALL = Calibration(ask_min_score=0.66, cluster_join_cosine=0.80, cluster_entity_cosine=0.66, dedupe_semantic_cosine=0.95, paragraph_cosine=0.93)
BGE_M3 = Calibration(ask_min_score=0.52, cluster_join_cosine=0.70, cluster_entity_cosine=0.52, dedupe_semantic_cosine=0.93, paragraph_cosine=0.92)

CALIBRATIONS: dict[str, Calibration] = {
    "bge-small-en-v1.5": BGE_SMALL,
    "bge-m3": BGE_M3,
}

def calibration_for(name: str) -> Calibration:
    return CALIBRATIONS.get(model_key(name), BGE_SMALL)
A model that isn't listed keeps bge-small's numbers, which is exactly what the code did before this table existed. Nothing changes for the ONNX, hash or API providers.
Two overrides survive. ASK_BLOG_MIN_SCORE still beats the table. And the admin Settings page stores a paraphrase cutoff whose default (0.93) was bge-small's. That default now means "the model's own cutoff", and any other value is treated as a deliberate choice and used as it is.
Step 3: measuring the new cutoffs
The bge-m3 row isn't guessed. It's measured on the news desk's own data, with a method I'd use again: quantile mapping.
The two models' cosines aren't on the same scale, but on the same pairs of texts they rank alike. Here the Spearman correlation was 0.770. So a cutoff keeps its meaning if it keeps the same share of pairs above it. If bge-small's 0.80 passes 1.53% of pairs, bge-m3's cutoff is the cosine that passes the same 1.53% of the same pairs.
scripts/calibrate_embeddings.py did this on 19 November 2026:
- 189 items (title and summary, embedded exactly as at ingest) from the desk's seven default feeds;
- all 17,766 pairs of those items, for the cluster cutoffs;
- each item paired with a reworded copy of itself (sentence order changed, every eighth word dropped, a different title prefix), for the high tail: dedupe and the paraphrase gate.

| Cutoff | bge-small | Pairs above | bge-m3 (mapped) | In the table | Agreement F1 |
|---|---|---|---|---|---|
cluster_entity_cosine | 0.66 | 22.4% | 0.523 | 0.52 | 0.679 |
cluster_join_cosine | 0.80 | 1.53% | 0.699 | 0.70 | 0.865 |
paragraph_cosine | 0.93 | 1.03% | 0.916 | 0.92 | 0.978 |
dedupe_semantic_cosine | 0.95 | 1.00% | 0.933 | 0.93 | 0.961 |
Agreement F1 compares the two decisions on the same pairs: how often both models put a pair on the same side of their cutoff.
Two things stand out:
- bge-m3 pushes unrelated items further apart (pair median 0.47 against 0.61) while keeping copies just as close (0.97 against 0.98). So the low cutoffs move a lot and the high ones barely move.
- The entity cutoff agrees least (F1 0.68). That's the "loosely related, and they share a named entity" zone, where two models are most likely to disagree about what's related. It's the cutoff I'll watch first once real clusters form.
Quantile mapping has a limit: it carries bge-small's behaviour over to bge-m3. It doesn't prove that behaviour was right. That's the right goal for a model swap, since nothing should change by accident. Better cutoffs would need labelled pairs, and that's a separate project.
Step 4: the Ask floor is measured, not mapped
Ask the Blog's floor is different. Its bge-small value came from rag_eval.py: 95 labelled questions run against the real index, and the calibrated floor is the highest cosine that loses no expected answer. bge-m3 gets the same treatment. Until that run finishes, the table's 0.52 is an interim value, bge-small's 0.66 mapped by quantile like the others.
Here is the comparison as it stands (configuration token-vector-div, the production setting):
| Model | Chunks | Recall@1 (%) | Recall@3 (%) | Recall@6 (%) | MRR | Calibrated floor |
|---|---|---|---|---|---|---|
| bge-small (ONNX), 19 Nov | 2,117 | 81.0 | 90.5 | 95.2 | 0.865 | 0.59 |
| bge-m3 (Ollama) | 2,117 | TODO | TODO | TODO | TODO | TODO |
One side finding: today's run puts bge-small's own floor at 0.59, below the 0.66 that production pins. The floor moves as articles and questions are added, which is one more reason to measure it rather than carry a number forward.
The rule I set for myself: jithendar.com doesn't switch providers until the bge-m3 floor is measured, either into the table or as ASK_BLOG_MIN_SCORE.
Step 5: migrating the news desk in place
The news desk was the part most likely to break. Its stored vectors are 384-dimensional, and:
- the clusterer would raise an error comparing a 1024-d item with a 384-d centroid;
- the topic classifier, trained on 384-d vectors, would silently cut 1024-d input down to 384.
Neither could be fixed with a one-off script, because the desk keeps running while the model changes. So the desk now notices stale vectors and repairs them as it goes. A stored vector is stale when its length differs from the current model's dimension:
# app/news/desk.py (excerpt)
def _stale(v: Any, dim: int) -> bool:
    """A stored vector of another size than the current model's: another model made it."""
    return bool(dim) and bool(v) and len(v) != dim

# Stale vectors re-embedded per call, newest rows first: mk4's CPU bge-m3 does about one item a second, and a 14-day
# window can hold thousands, which must not stretch one run past its timeout. The rest follow on the next runs.
REEMBED_PER_RUN = 200
On every run after the switch:
- Window items with stale vectors are re-embedded, at most 200 per run and newest first. The rest are compared by text only in that run: their old vectors are dropped in memory, not in the table, until their turn comes.
- Cluster centroids of the old size are rebuilt from their members' current vectors (the normalised mean), not thrown away.
- The classifier, still trained on 384-d vectors, falls back to rules. A newly trained model would normally have to beat the serving one on macro-F1 to be promoted, but those scores can't be compared across vector sizes. So a model trained on the new size is promoted, with a note saying why.
- Labelled items outlive the window, so training re-embeds up to 400 of them per run (about seven minutes on bge-m3). Any still stale are left out of that training and picked up next time.
Using the vector's length as the model marker is crude but robust. It needs no extra column, and it can't drift out of sync with the data.
The quality gate needs no migration, since it embeds a draft's paragraphs fresh each time. It does get slower: it compares up to 300 source paragraphs per draft, which was instant with bge-small and takes a few minutes with bge-m3 on CPU.
Step 6: build the new index, then swap
The article index can't migrate in place: vector(384) can't hold a 1024-d vector. So when seo-agent sees a dimension change, it leaves the live table alone and creates seo_article_chunks_next at the new size. The next complete reindex fills it, and then it replaces the live table in one transaction:
# app/index.py (excerpt)
async def _swap(self, c: Any) -> None:
    """The rebuilt table replaces the live one in one transaction: readers see the old table or the new, never none."""
    async with c.transaction():
        await c.execute(f"drop table {LIVE_TABLE}")
        for ddl in _SWAP_RENAMES:
            await c.execute(ddl)
        # ...rename leftover constraints, e.g. PostgreSQL 18's named NOT NULL constraints
There's a cost. Between the switch and the swap, question vectors (1024-d) no longer fit the live table (384-d), so Ask the Blog answers with its fallback ("no article on this yet") for the length of the reindex: about 50 minutes for 2,117 chunks at 0.7 chunks a second. It's a one-off window, so it's worth starting at a quiet hour. If the switch is reverted mid-way, the half-built table is dropped and the old one keeps serving. The LanceDB copy of the index rewrites itself at the new size on the same reindex.
The rollout, and the merge that broke master

The code went in as two pull requests, and the first one was merged too early.
moks-seo-agent#8 carried the provider, the calibration table, the news desk migration and the scripts. It was opened as a draft, because the bge-m3 row of the calibration table didn't exist yet: the measurements were still running. Its new tests asserted that the row existed, so they were meant to fail until it did. It was merged anyway, and master's check failed four tests with KeyError: 'bge-m3'.
Nothing reached production, for a simple reason: seo-agent's CI builds and smoke-tests the release image while the merge's tests run, but pushes it only if they pass. A red master meant no image, so the half-finished change never ran. moks-seo-agent#9 added the measured row 27 minutes later, master went green, and the image that runs on mk4 today has both.
Two lessons from that hour:
- Tests that pin a contract are worth writing before the data exists. "Every model we can switch to has a calibration row" is the kind of rule that's easy to forget. A failing test made forgetting impossible.
- Gate the release on the tests, not just the merge. A merge button pressed early is a human mistake. A release that ships whatever was merged turns that mistake into an outage.
The order of the remaining steps matters too. The new image had to be running before the config switch, because the old image's Ollama provider would have created a 768-dimension table. That's done. What's left is the measurement and then the switch itself, a small change in the jithendar.com repository:
# kubernetes/seo-agent-40-seo-agent.yaml (prepared change)
EMBEDDINGS_PROVIDER: ollama
OLLAMA_URL: http://bge-m3.embeddings:11434
OLLAMA_EMBED_MODEL: bge-m3:567m
# ASK_BLOG_MIN_SCORE removed: the floor now follows the model (app/calibration.py)
It also adds an egress rule to embeddings:11434 to seo-agent's NetworkPolicy. Then: restart seo-agent, run a full reindex, and let the news desk catch up over its next runs. To roll back, set EMBEDDINGS_PROVIDER: onnx and reindex. bge-small is still in the image.
What I'd tell myself before starting
- A model change is a data migration. List every place a vector is stored or a cosine is compared before touching the config.
- Put cutoffs next to the model. A cosine cutoff without a model name is a bug waiting for the next model.
- Map cutoffs on your own data. Seven feeds and 189 items were enough to move four cutoffs with evidence instead of intuition.
- Measure what users see. The Ask floor goes through the labelled evaluation set, and the switch waits for it.
- Let stored data heal gradually. Bounded re-embedding per run, newest first, kept every run inside its timeout while the desk kept working.
Discussion comments
No comments yet. Start the discussion.